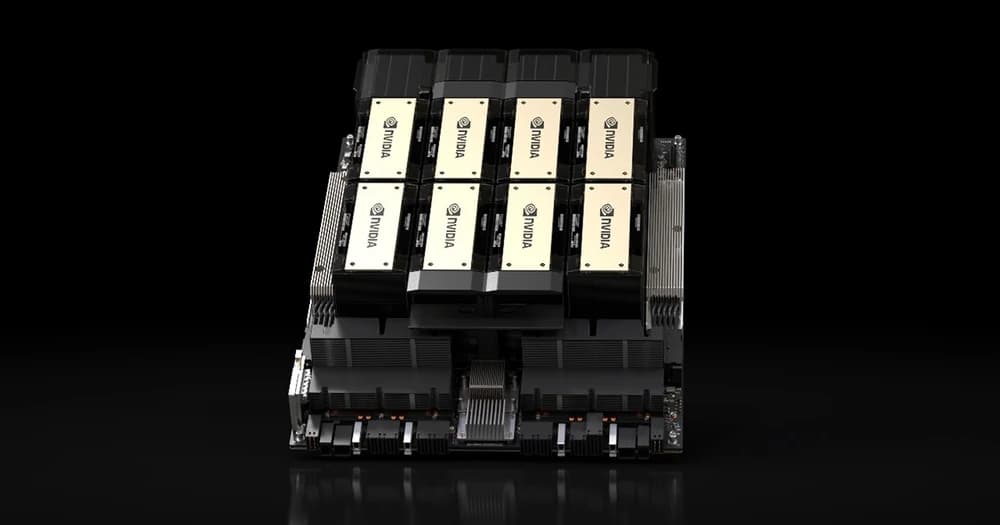
NVIDIA's GPU lineup for AI has never been more capable, or more confusing. The H100, H200, and B200 each represent significant architectural advances, but choosing between them requires understanding not just raw specifications but how those specifications translate to workload performance and cost per unit of work.
This guide compares the three on specifications, pricing, and cost-efficiency, with arithmetic you can check yourself. For how these GPUs are priced across providers, see the 2026 GPU cloud comparison.
Methodology and Assumptions
This article is in the benchmarks category, so it is worth being precise about what the numbers are and are not:
- Prices are GPUVerse catalog floor prices as of August 2026, the lowest observed marketplace/neocloud "from" rate per GPU-hour: H100 SXM from $1.99, H100 PCIe from $2.49, H200 from $2.89, B200 from $5.49. Hyperscaler on-demand rates run well above these floors.
- Specifications come from NVIDIA vendor spec sheets. Tensor TFLOPS figures are quoted with sparsity; dense throughput is half the quoted number.
- Throughput and latency figures are illustrative estimates, not lab benchmarks run by GPUVerse. They assume a modern serving stack (vLLM or TensorRT-LLM class) and are stated with their assumptions so you can substitute your own measurements.
- All $/M-token figures use the published formula: cost per 1M tokens = (price per hour ÷ (tokens/sec × 3,600)) × 10⁶.
GPU Architecture Overview
H100: The Workhorse
The H100 Tensor Core GPU, based on the Hopper architecture, became the de facto standard for AI training and inference after its 2022 launch. Key specifications:
| Specification | H100 SXM | H100 PCIe |
|---|---|---|
| FP32 Performance | 67 TFLOPS | 51 TFLOPS |
| FP16 Tensor (with sparsity) | 1,979 TFLOPS | 1,513 TFLOPS |
| HBM3 Memory | 80GB | 80GB |
| Memory Bandwidth | 3.35 TB/s | 2.0 TB/s |
| NVLink Bandwidth | 900 GB/s | 600 GB/s (NVLink bridge) |
| TDP | 700W | 350W |
Dense FP16 throughput is half the sparse figure, roughly 990 TFLOPS for the SXM and 756 TFLOPS for the PCIe part.
The H100 excels at training workloads and large-scale inference. Its NVLink interconnect enables efficient multi-GPU configurations, and its transformer engine provides hardware acceleration for attention-based models.
H200: The Memory Leap
The H200 is architecturally similar to the H100 but with a critical upgrade: HBM3e memory delivering 141GB at 4.8 TB/s bandwidth. That is 76% more memory capacity and 43% more bandwidth than the H100 SXM, at identical compute TFLOPS.
For inference workloads, the H200's memory characteristics matter most:
- Larger batch sizes: Fit larger models or more requests per GPU
- Longer context windows: Serve models with 128K+ context lengths without splitting
- Improved throughput: Higher memory bandwidth directly translates to faster token generation in bandwidth-bound decode
| Specification | H100 SXM | H200 141GB |
|---|---|---|
| Memory | 80GB HBM3 | 141GB HBM3e |
| Bandwidth | 3.35 TB/s | 4.8 TB/s |
| FP16 Tensor (with sparsity) | 1,979 TFLOPS | 1,979 TFLOPS |
| Price premium (catalog floors, Aug 2026) | Baseline ($1.99/hr) | ~45% ($2.89/hr) |
Note the premium: at catalog floor prices as of August 2026, the H200 ($2.89/hr) costs about 45% more per hour than the H100 SXM ($1.99/hr). Whether that premium pays for itself depends entirely on whether your workload is memory-bound, the cost analysis below works through it.
B200: The Current Flagship
The Blackwell architecture B200 is NVIDIA's current-generation flagship, designed for the next wave of AI demands:
| Specification | B200 |
|---|---|
| FP16 Tensor (with sparsity) | 2,250 TFLOPS |
| FP8 Tensor (with sparsity) | 4,500 TFLOPS |
| HBM3e Memory | 192GB |
| Memory Bandwidth | 8.0 TB/s |
| TDP | 1,000W |
The B200's low-precision capabilities enable efficient inference for large language models, and its 192GB memory capacity can fit models that would require multiple H100s.
The B200 is the current-generation flagship with growing availability across providers in 2026, catalog floor pricing starts at $5.49/hr as of August 2026. Supply is tighter than for Hopper-generation parts, and large allocations may still require reservations, but B200 capacity is no longer an early-access rarity.
Workload-Specific Recommendations
Training Workloads
For training large models from scratch or fine-tuning existing models, the H100 remains the standard choice in 2026:
Why H100 for training:
- Mature software ecosystem (CUDA, cuDNN, transformer engine optimizations)
- Excellent multi-GPU scaling via NVLink (900 GB/s per GPU on SXM)
- Proven reliability in production training environments
- More competitive pricing as volume has increased
When to consider H200 for training:
- Datasets require extremely large batch sizes that exceed H100 memory
- Fine-tuning models with very long context windows
- Research environments where H200 availability matches training needs
Inference Workloads
Inference presents a more nuanced choice:
For standard LLM inference (7B–70B models):
- H200 offers strong cost-efficiency due to memory capacity, a 70B model in FP16 fits on a single H200 with room for KV cache
- Higher batch sizes improve GPU utilization
- Longer context windows without memory pressure
For very large models (100B+ parameters):
- Multi-H100 configuration remains the practical choice
- B200 becomes attractive for single-GPU serving of 100B+ models in low precision
For batch inference with fixed deadlines:
- H100 on-demand or spot offers strong price-performance
- Interruptions are tolerable with proper checkpointing, see our spot instances guide
Real-Time Inference Requirements
For latency-sensitive inference (p99 < 100ms), memory bandwidth is usually the deciding factor, because decode-phase latency per token is bandwidth-bound. The figures below are illustrative, assuming a 70B model in FP8, batch size 4, 512-token prompts, on a TensorRT-LLM-class stack, treat the ordering as the signal, not the absolute values, and benchmark your own stack:
| Configuration | Illustrative decode latency (70B, 512-token input) |
|---|---|
| H100 SXM | ~45ms |
| H200 141GB | ~38ms |
| B200 | ~32ms |
The ordering follows memory bandwidth: 3.35 TB/s → 4.8 TB/s → 8.0 TB/s. For user-facing real-time applications, the H200's bandwidth advantage over the H100 is the main reason to pay its premium.
Cost Efficiency Analysis
Raw GPU performance matters less than cost-adjusted performance. Here is one coherent comparison for a realistic inference workload.
Scenario: serving Llama 3.1 70B, roughly 10M tokens/day. A 70B model in FP16 needs ~140GB for weights alone, so it does not fit on a single 80GB H100, the H100 option is a 2-GPU tensor-parallel pair, while the H200 (141GB) and B200 (192GB) serve it on one GPU. Throughput figures are illustrative estimates for a batched vLLM-class stack in FP8; prices are catalog floors as of August 2026.
| Configuration | $/hour | Illustrative throughput | $/M tokens |
|---|---|---|---|
| 2× H100 SXM ($1.99 each) | $3.98 | 900 tok/s aggregate | $1.23 |
| 1× H200 ($2.89) | $2.89 | 800 tok/s | $1.00 |
| 1× B200 ($5.49) | $5.49 | 1,400 tok/s | $1.09 |
The arithmetic, so you can check it:
- 2× H100 SXM: $3.98 ÷ (900 × 3,600) × 10⁶ = $1.23/M tokens
- 1× H200: $2.89 ÷ (800 × 3,600) × 10⁶ = $1.00/M tokens
- 1× B200: $5.49 ÷ (1,400 × 3,600) × 10⁶ = $1.09/M tokens
At these assumptions the H200 is about 18% cheaper per token than the H100 pair, despite its 45% higher per-GPU floor price, the single-GPU deployment avoids paying for two GPUs and tensor-parallel communication overhead. The B200 delivers the most absolute throughput but its $5.49/hr floor keeps it slightly behind the H200 on cost per token for this model size; it pulls ahead when you need its 192GB or its throughput headroom.
Running 24/7 at floor prices (730 hours/month): the H100 pair costs $2,905/month, the H200 $2,110/month, and the B200 $4,008/month. At 10M tokens/day the fleet is far from saturated, so real-world cost per token depends heavily on utilization, an underutilized cheaper-per-token GPU can still cost more per month than a right-sized one.
Making the Selection
The decision framework:
-
Check availability first: H100 and H200 have broad provider support; B200 availability is growing but larger allocations may need reservations.
-
Assess memory requirements: If your model plus batch fits in H100 memory, the H100's lower floor price is a significant advantage.
-
Evaluate latency requirements: For real-time applications where latency directly impacts user experience, the H200's bandwidth advantage justifies its ~45% price premium.
-
Consider multi-GPU scaling: If a model does not fit on one H100, compare the 2× H100 cost against a single H200 before defaulting to more H100s.
For most organizations in 2026: use H100 for training workloads, H200 for inference workloads where memory or latency are constraints, and evaluate B200 when you need 192GB on one GPU or maximum throughput. GPUVerse's decision engine runs this comparison across all 10 providers and 54 accelerators automatically.
Conclusion
The H100 vs H200 vs B200 decision comes down to matching workload characteristics to hardware: compute-bound training favors the H100's price, memory-bound inference favors the H200's capacity and bandwidth, and the largest models or highest throughput targets favor the B200.
The gap between spec sheets and real-world performance is bridged by understanding your workload. GPUVerse's scoring engine incorporates these nuances automatically, but understanding the fundamentals helps you ask the right questions and interpret the recommendations.
FAQ
Is the H200 worth its price premium over the H100?
At August 2026 catalog floors, the H200 ($2.89/hr) carries a ~45% premium over the H100 SXM ($1.99/hr). For memory-bound inference, models that need two H100s but one H200, or long-context serving, it typically comes out cheaper per token. For compute-bound training that fits in 80GB, the H100 usually wins.
Are the quoted TFLOPS figures real-world throughput?
No. Tensor TFLOPS figures (e.g., 1,979 TFLOPS FP16 for H100 SXM and H200) are vendor spec-sheet numbers with sparsity; dense throughput is half that, and real workload throughput is lower still. Use them for relative comparison, not capacity planning.
What is the difference between H100 SXM and H100 PCIe?
The SXM part has higher memory bandwidth (3.35 vs 2.0 TB/s), higher FP16 tensor throughput (1,979 vs 1,513 TFLOPS with sparsity), 900 GB/s NVLink versus a 600 GB/s NVLink bridge, and a 700W versus 350W TDP. As of August 2026 the SXM floor price ($1.99/hr) actually sits below the PCIe floor ($2.49/hr), a marketplace supply quirk, not a typo.
Can a single GPU serve Llama 3.1 70B?
In FP16 the weights alone need ~140GB, so no single 80GB H100 can hold them, you need two H100s or quantization. A single H200 (141GB) or B200 (192GB) can serve the model on one GPU with room for KV cache.
Is the B200 generally available in 2026?
Yes, the B200 is the current-generation flagship with growing availability, with catalog floor pricing from $5.49/hr as of August 2026. Supply remains tighter than Hopper parts and large allocations may require reservations.